A research assistant that indexes your PDFs and answers with citations, without uploading anything.
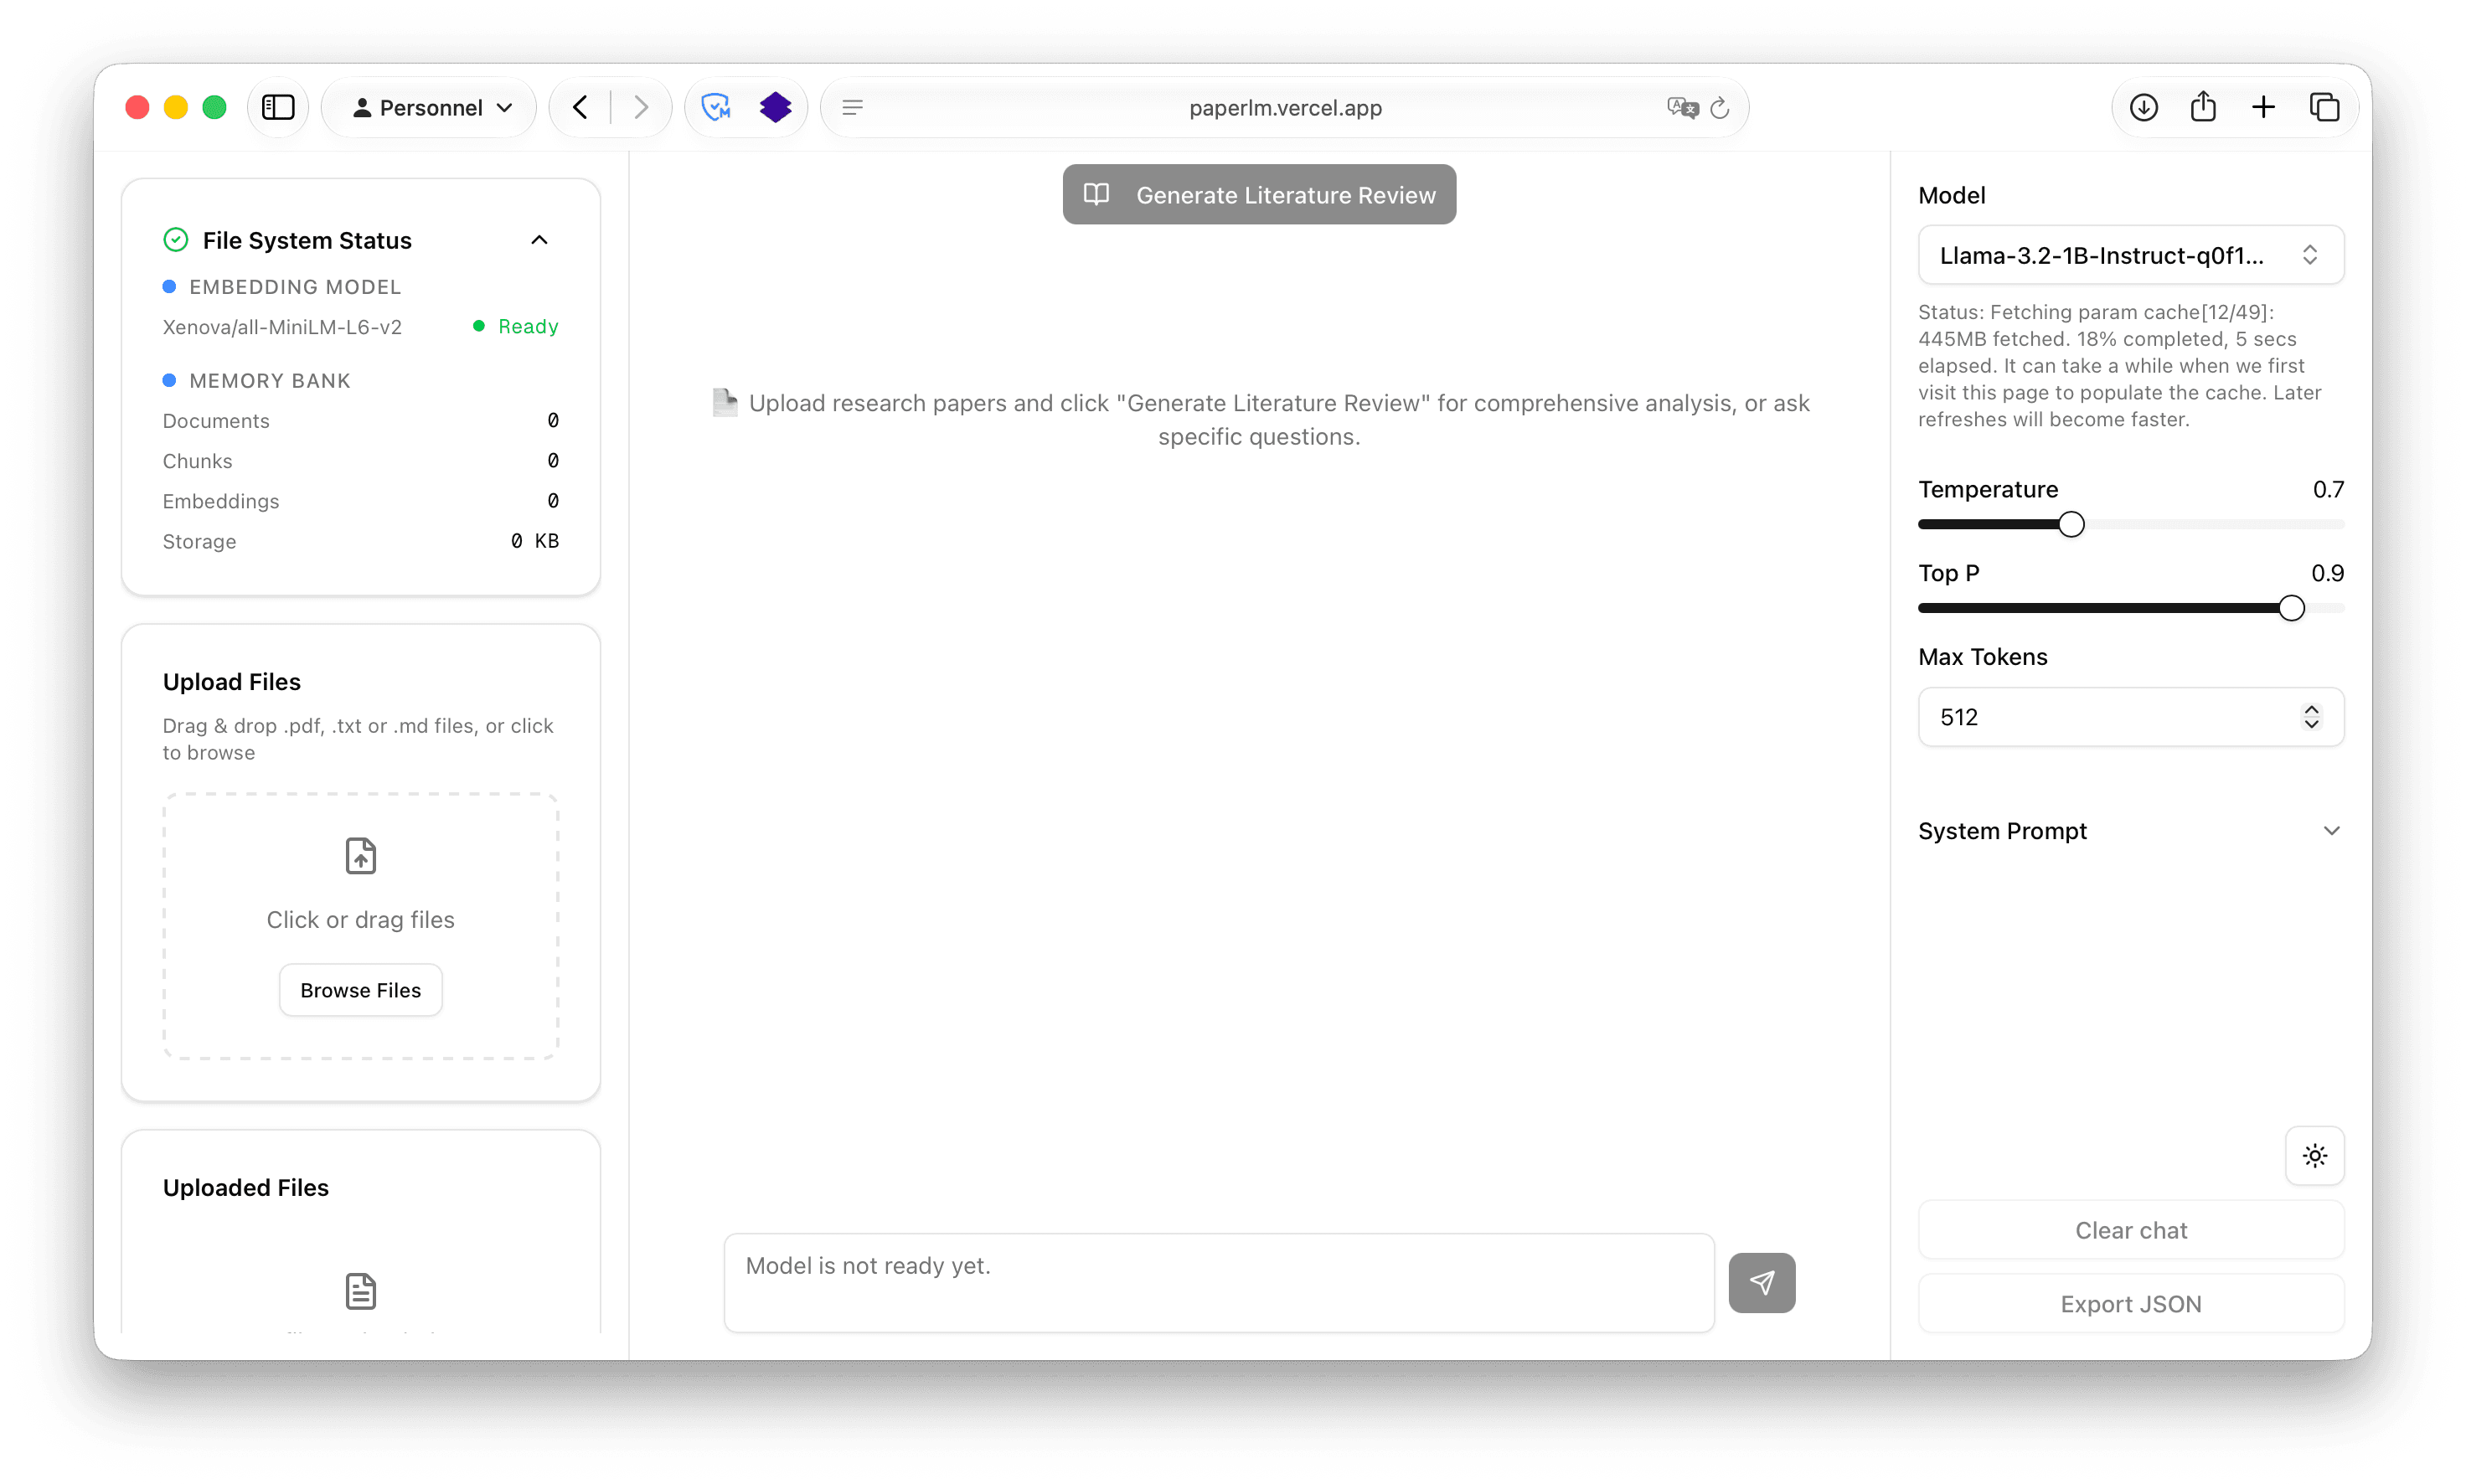
PaperLM turns a pile of papers into a literature review without uploading a single page. Drop PDFs into the sidebar and the pipeline runs client-side: PDF.js extracts the text, it is chunked and each chunk is embedded with all-MiniLM-L6-v2 through Transformers.js, then the passages relevant to your question are retrieved and handed to Llama 3.2 1B running locally through MLC WebLLM. Answers stream back grounded in those passages and cite the documents they came from, and a single button produces a longer structured review instead of a chat reply.
The constraint is the interesting part. Because inference runs on the consumer GPU through WebGPU, the real limits are model size, context length and how fast the browser streams tokens — not server throughput. Choosing a 1B model, chunking aggressively enough to keep retrieval relevant, and accepting a first-token delay were the three decisions that shaped the rest.